Turnkey AI & High-Performance Computing Infrastructure
Patel Galaxify Solutions supplies, stages, and deploys high-density GPU compute servers, low-latency InfiniBand fabrics, and parallel NVMe storage for enterprise machine learning, research clusters, and data-intensive computing across India.
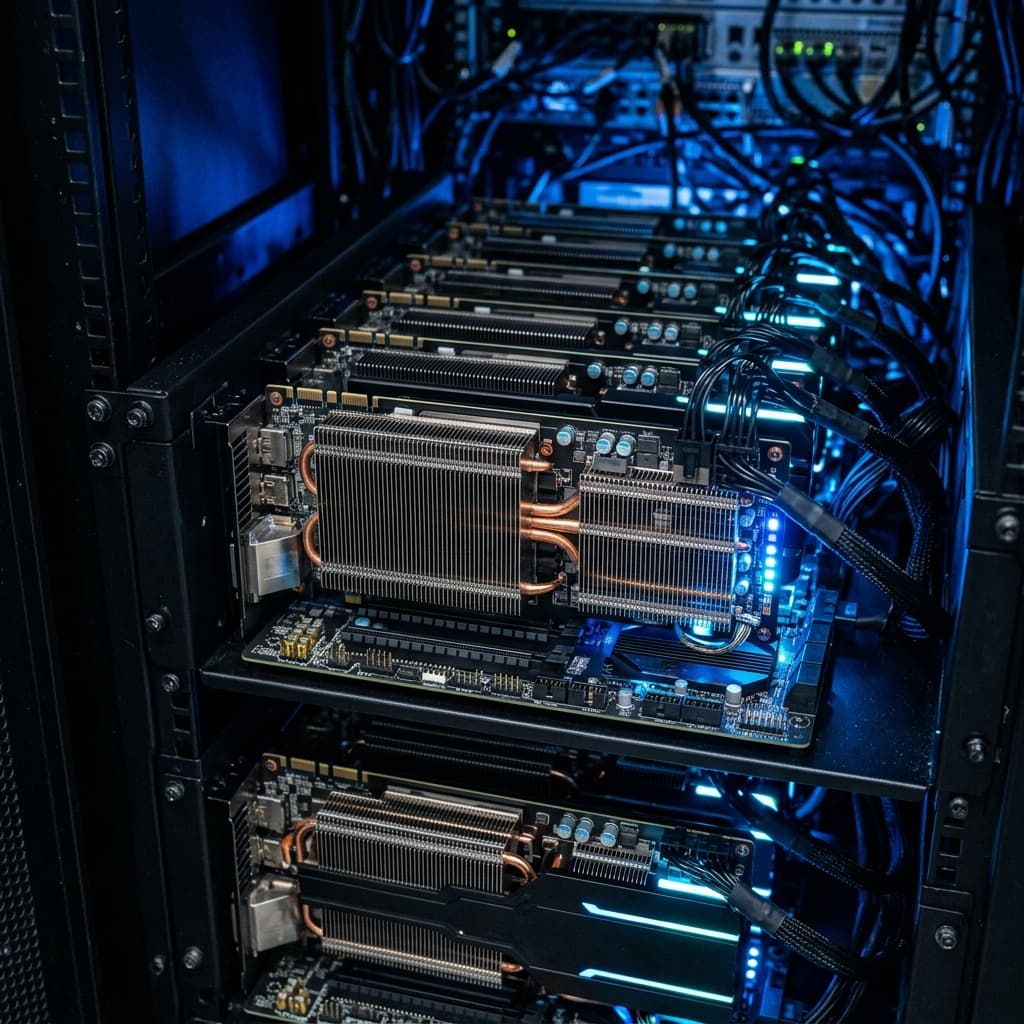
High-Density GPU Node Architecture
Multi-accelerator topology with high-speed PCIe 5.0 lanes
Enterprise AI & HPC Infrastructure Capabilities
Building modern AI computing clusters requires specialized hardware across multiple disciplines. We engineer and supply every layer of the compute cluster stack.
High-Density GPU Compute Nodes
Sourcing and deploying multi-GPU server architectures supporting NVIDIA HGX and PCIe accelerators (including H100, H200, L40S, and A100 classes). Engineered for intense deep learning, tensor mathematics, and parallel execution.
AI Training vs. Inference Architectures
Differentiating dense, high-bandwidth interconnected nodes for foundational model training and parameter fine-tuning from energy-efficient, low-latency 1U/2U configurations designed for production model inferencing.
Ultra-Low Latency Fabric & Interconnect
Eliminating inter-node bottlenecks with non-blocking 400Gb/s InfiniBand and high-speed RoCE (RDMA over Converged Ethernet) fabrics. Enables GPUDirect RDMA for seamless memory-to-memory communication across cluster nodes.
All-Flash Parallel Storage Integration
Supplying high-throughput NVMe parallel storage tiers capable of saturating multi-GPU ingestion pipelines during training runs, paired with high-capacity secondary storage for massive raw datasets and checkpointing.
Turnkey Rack Integration & Cabling
Certified staging, rack elevation design, and structured cabling for high-density environments. Our engineers handle precision mounting, rail installations, and clean airflow dressing in standard 42U and 48U enclosures.
Power Density & Thermal Engineering
AI clusters operate at significantly higher power densities than standard enterprise workloads. We assist teams in planning power phase balancing, three-phase intelligent PDUs, and cold-aisle thermal containment.
Interconnected Infrastructure Architecture
AI performance is determined by the weakest link in the cluster. Below is an illustrative breakdown of how compute, networking, storage, power, and orchestration integrate into a balanced enterprise AI factory.
* Note: Sample architecture is illustrative. Final configuration is custom-sized to workload specs.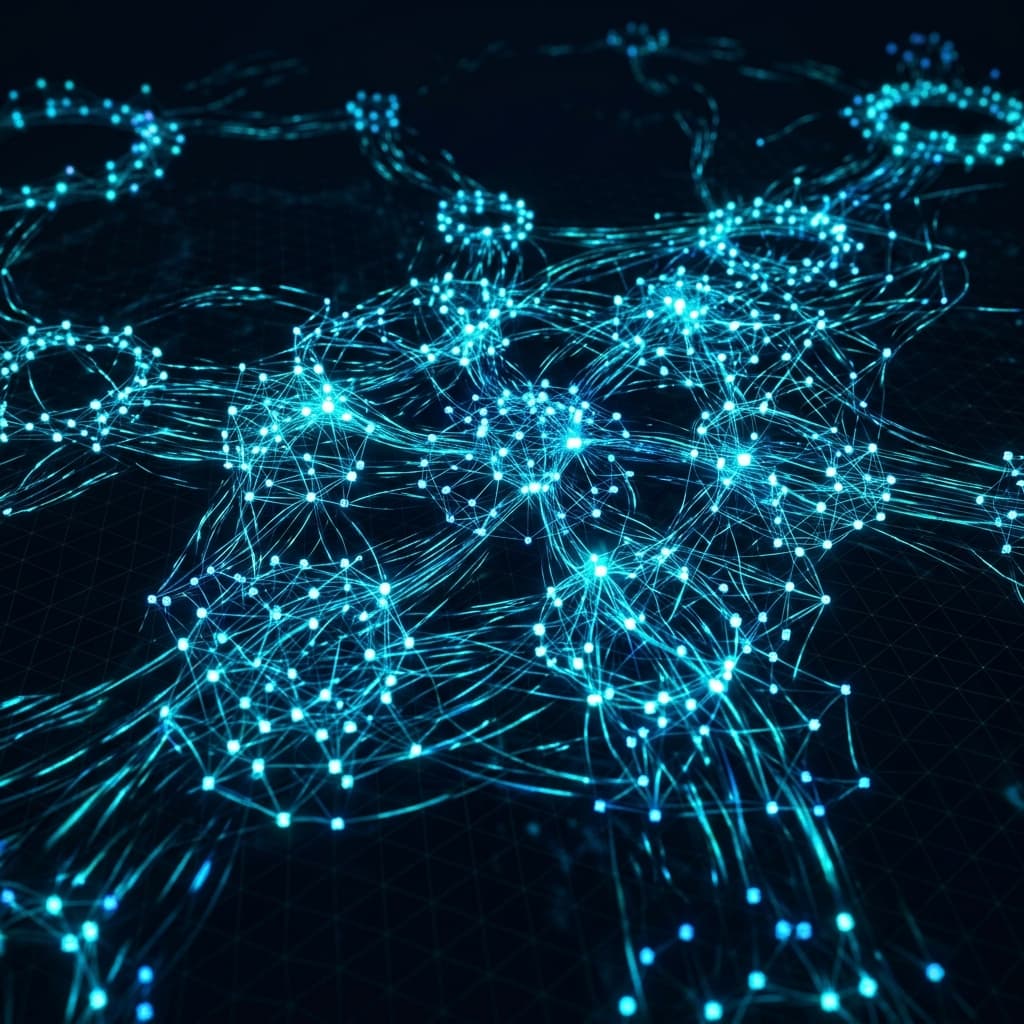
Full-Stack AI Cluster Fabric
High-density compute nodes interconnected by low-latency spine-leaf network
Architecture Sizing Principle
We balance PCIe 5.0 root complexes, memory channels per socket, and GPU-to-NIC topology to eliminate starvation during distributed all-reduce operations.
GPU & Host Compute Layer
Enterprise GPU servers equipped with high-density accelerators connected via high-speed internal crossbars (NVLink/NVSwitch). Powered by high-TDP multi-core x86 processors providing memory channels and PCIe 5.0 root complexes.
Interconnect & Cluster Fabric
Dedicated high-bandwidth fabric switches enabling distributed all-gather and all-reduce collective communications across nodes without CPU intervention through GPUDirect RDMA.
Parallel Data Ingestion & Storage
Multi-tiered enterprise storage architecture. Ultra-fast NVMe flash feeds training data directly into accelerator memory to keep GPU utilization near 100%, backed by petabyte-scale storage arrays for deep archives.
Power, Cooling & Physical Enclosure
Heavy-duty enterprise racks engineered to handle concentrated physical weight, dual-redundant 3-phase power feeds, intelligent circuit-level metering, and structured airflow containment.
Cluster Orchestration & Systems Layer
Commissioned base system software stack including bare-metal OS hypervisors, GPU driver toolkits, fabric diagnostics, and orchestration frameworks ready for client workload schedulers.
Engineered for Demanding Enterprise Workloads
Different computational workloads stress hardware in distinct ways. We tailor hardware bills of materials to your exact algorithmic and dataset demands.
Generative AI & LLM Engineering
Infrastructure sized for distributed parameter training, parameter-efficient fine-tuning (LoRA), and high-concurrency API inferencing of foundation models.
8-Way HGX GPU nodes, NDR InfiniBand fabric, high-throughput NVMe storage
Computer Vision & Autonomous Systems
High-throughput parallel processing clusters for video frame extraction, object detection models, defect inspection, and real-time inference at scale.
PCIe and HGX GPU compute, multi-channel 25G/100G Ethernet ingest
Scientific Simulation & Genomics
Massive memory footprints and double-precision floating-point performance for computational fluid dynamics (CFD), molecular docking, and genomic alignment.
Dual-socket high-core compute nodes, MPI-optimized low-latency InfiniBand
Financial Modeling & Algorithmic Trading
Ultra-low-latency deterministic compute clusters for Monte Carlo options simulations, tick-by-tick market data backtesting, and real-time risk assessment.
Dense high-frequency compute, FPGA/GPU acceleration, low-latency switching
Accelerated Data Analytics & Vector Search
Accelerating columnar database queries, distributed vector indexing, and embedding search over multi-terabyte enterprise knowledge bases.
Large host system RAM, NVMe flash arrays, high-density PCIe GPUs
From Workload Sizing to On-Site Validation
High-value AI hardware demands rigorous engineering discipline. Our phased deployment model protects your capital investment and ensures day-one operational stability.
Workload Discovery & Sizing
We analyze your target models, dataset sizes, concurrency requirements, and budget constraints to calculate necessary GPU counts, memory bandwidth, and power draw.
Architecture Design & BOM Formulation
Our infrastructure specialists generate an optimized, vendor-neutral Bill of Materials (BOM) specifying servers, GPUs, interconnects, optical cables, and power components.
Authorized Technology Sourcing
Procuring 100% genuine hardware through verified national distributor channels with direct manufacturer warranties, formal tax invoices, and insured freight.
Staging, Rack Mounting & Cabling
Physical rack installation, component burn-in, structured cabling dressing, PDU phase balancing, and clean data center power-on by certified technicians.
Fabric & Driver Validation
Initialization and verification of hardware health, out-of-band management (BMC/IPMI), InfiniBand link integrity, and NVIDIA NCCL all-reduce bandwidth testing.
Handover & Lifecycle Support
Comprehensive documentation handover, warranty registration, and tailored Annual Maintenance Contracts (AMC) with dedicated replacement parts logistics.
Technical Discovery Checklist for RFQ
Preparing to issue an inquiry or tender? These 8 critical technical parameters ensure our infrastructure team can return an exact, commercially viable hardware specification.
Target Workloads & Frameworks
Accelerator Architecture (HGX vs. PCIe)
Host Processor & System Memory
Inter-Node Interconnect Bandwidth
Dataset Volume & Ingestion Speed
Data Center Power & Thermal Budget
Physical Enclosure Space & Location
Budget Parameters & Procurement Window
Enterprise AI & HPC Infrastructure FAQ
Common questions from enterprise IT heads, engineering managers, and procurement committees regarding sizing, supply, and support.
Does Patel Galaxify Solutions supply complete AI server hardware or software development?
How do you determine whether we need SXM/HGX nodes or PCIe GPU servers?
What typical lead times should we anticipate for enterprise GPU hardware?
Can Patel Galaxify Solutions deploy AI hardware at our third-party colocation data center?
What ongoing support and maintenance options do you provide for AI clusters?
How does Patel Galaxify Solutions ensure genuine hardware with valid warranty?
Related Infrastructure Solutions
Enterprise Servers & Computing
1U–4U rack servers, multi-node compute clusters, and mission-critical x86 computing.
Enterprise Storage Solutions
SAN, NAS, and unified All-Flash NVMe arrays delivering massive IOPS for data pipelines.
Enterprise Networking Fabric
High-speed spine-leaf 100G/400G switching, optics, and low-latency data center fabrics.
Data Center Infrastructure
Heavy-duty server enclosures, intelligent three-phase PDUs, and cabling systems.
Ready to Size & Procure Your AI/HPC Cluster?
Send our technical infrastructure desk your target workloads, desired GPU specifications, or formal RFP. We return validated Bill of Materials (BOM), power/thermal sizing, and competitive commercial pricing.